Godot Version
v4.7.2
Question
I’m currently working on a top-down procedural cave generation system which uses a noise map to place wall tiles (that have collision) and floor tiles (that do not have collision but have a navigation layer) on a tile map layer node. I am running into some issue with performance that i believe are caused by how i am handling the generation of the navigation region withing the cave.
Currently, the process is: A navigation region 2d is baked passing in the tile map layer’s static colliders. and is re-baked every time new tiles are loaded or if a wall tile is turned into a floor tile (which would happen frequently during run time).
So far I’ve tried separating the navigation region into many smaller ones that cover a single chunk, then only re-baking the one in the chunk being updated. this turned out to run worse.
There is likely some performance being lost in how i get the geometry passed into the navigation region (navigation layers in the floor tiles) but I’m unsure on what other method i could use to bake the navigation mesh.
Any other ideas on how to improve this process would be greatly appreciated.
Update on this in case anyone stumbles on this later.
I have found a solution, turns out i never even needed a navigation region node, i could just use the navigation layers of the floor tiles as a navigation map, meaning i never need to bake a navigation region, there will simply be new areas for things to navigate to whenever a floor is added.
i set the navigation agent post-processing to edgecenter so that things wouldn’t get stuck on walls, and changed the following line:
	#old:
	nav2d.target_position = NavigationServer2D.region_get_random_point(nav_region.get_rid(), 1, true)

	#new, atlas id of floors is 1, tile dimensions are 128x128px:
	nav2d.target_position = tile_map.get_used_cells_by_id(1).pick_random()*128.0
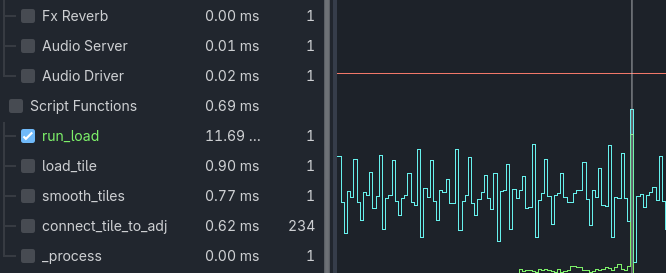
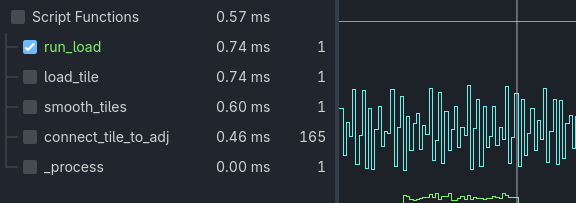
upon testing i noticed a complete lack in any spike inside the profiler upon loading 36 chunks (an unrealistic amount, usually at most 15 chunks can be loaded in one batch)
(red: physics process, blue: process)
previously:
now:
there is an increase in static memory usage with the new method but it is a difference of around 20mb.
overall this appears to be significantly better for performance and i will start using this method from now on.